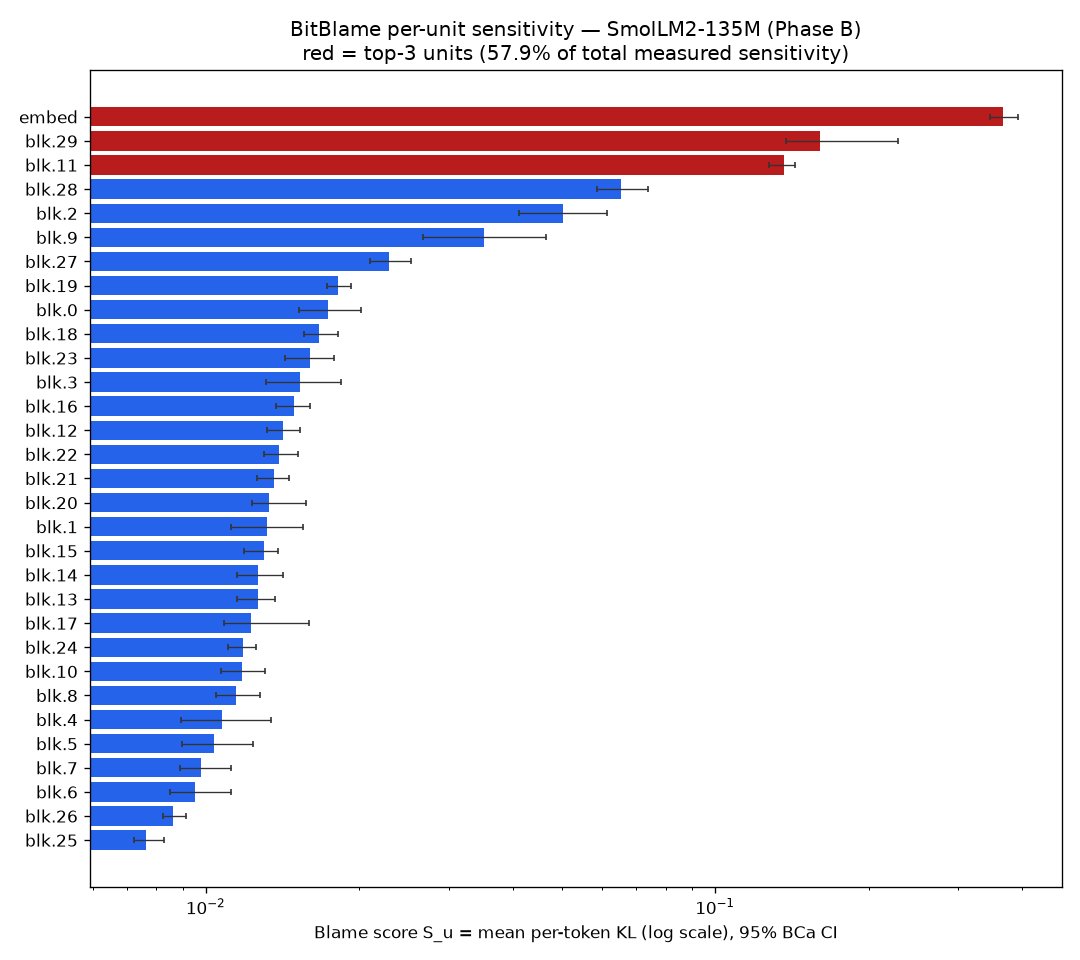
The measured recipe
Exact-DP knapsack over 6 real GGUF quant types, emitted as llama-quantize --tensor-type overrides.
Resulting GGUF: 94,373,920 B vs Q4_K_M baseline 105,453,856 B (ratio 0.8949 — 10.5% smaller).
Note: the output.weight=Q5_K line is a no-op on this tied-embedding model (no such tensor exists);
unmentioned tensors fall back to Q4_K_M. Full recipe file: recipe.sh in the dataset.
#!/bin/sh
# BitBlame recipe — measured-sensitivity-driven GGUF quantization
# Generated per METHODOLOGY.md §7.4 (spec v1.0).
# Unmentioned tensors fall back to the base type.
set -e

# 1) importance matrix on the calibration mix (§5.1)
llama-imatrix -m model-f16.gguf -f calib.txt -o imatrix.dat

# 2) quantize with per-tensor overrides (measured allocation)
llama-quantize --imatrix imatrix.dat \
  --tensor-type 'blk.0.attn_q.weight=Q5_K' \
  --tensor-type 'blk.0.attn_k.weight=Q5_K' \
  --tensor-type 'blk.0.attn_v.weight=Q5_K' \
  --tensor-type 'blk.0.attn_output.weight=Q5_K' \
  --tensor-type 'blk.0.ffn_gate.weight=Q5_K' \
  --tensor-type 'blk.0.ffn_up.weight=Q5_K' \
  --tensor-type 'blk.0.ffn_down.weight=Q5_K' \
  --tensor-type 'blk.10.attn_q.weight=Q2_K' \
  --tensor-type 'blk.10.attn_k.weight=Q2_K' \
  --tensor-type 'blk.10.attn_v.weight=Q2_K' \
  --tensor-type 'blk.10.attn_output.weight=Q2_K' \
  --tensor-type 'blk.10.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.10.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.10.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.11.attn_q.weight=Q8_0' \
  --tensor-type 'blk.11.attn_k.weight=Q8_0' \
  --tensor-type 'blk.11.attn_v.weight=Q8_0' \
  --tensor-type 'blk.11.attn_output.weight=Q8_0' \
  --tensor-type 'blk.11.ffn_gate.weight=Q8_0' \
  --tensor-type 'blk.11.ffn_up.weight=Q8_0' \
  --tensor-type 'blk.11.ffn_down.weight=Q8_0' \
  --tensor-type 'blk.13.attn_q.weight=Q2_K' \
  --tensor-type 'blk.13.attn_k.weight=Q2_K' \
  --tensor-type 'blk.13.attn_v.weight=Q2_K' \
  --tensor-type 'blk.13.attn_output.weight=Q2_K' \
  --tensor-type 'blk.13.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.13.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.13.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.14.attn_q.weight=Q2_K' \
  --tensor-type 'blk.14.attn_k.weight=Q2_K' \
  --tensor-type 'blk.14.attn_v.weight=Q2_K' \
  --tensor-type 'blk.14.attn_output.weight=Q2_K' \
  --tensor-type 'blk.14.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.14.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.14.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.17.attn_q.weight=Q2_K' \
  --tensor-type 'blk.17.attn_k.weight=Q2_K' \
  --tensor-type 'blk.17.attn_v.weight=Q2_K' \
  --tensor-type 'blk.17.attn_output.weight=Q2_K' \
  --tensor-type 'blk.17.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.17.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.17.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.18.attn_q.weight=Q5_K' \
  --tensor-type 'blk.18.attn_k.weight=Q5_K' \
  --tensor-type 'blk.18.attn_v.weight=Q5_K' \
  --tensor-type 'blk.18.attn_output.weight=Q5_K' \
  --tensor-type 'blk.18.ffn_gate.weight=Q5_K' \
  --tensor-type 'blk.18.ffn_up.weight=Q5_K' \
  --tensor-type 'blk.18.ffn_down.weight=Q5_K' \
  --tensor-type 'blk.19.attn_q.weight=Q5_K' \
  --tensor-type 'blk.19.attn_k.weight=Q5_K' \
  --tensor-type 'blk.19.attn_v.weight=Q5_K' \
  --tensor-type 'blk.19.attn_output.weight=Q5_K' \
  --tensor-type 'blk.19.ffn_gate.weight=Q5_K' \
  --tensor-type 'blk.19.ffn_up.weight=Q5_K' \
  --tensor-type 'blk.19.ffn_down.weight=Q5_K' \
  --tensor-type 'blk.2.attn_q.weight=Q6_K' \
  --tensor-type 'blk.2.attn_k.weight=Q6_K' \
  --tensor-type 'blk.2.attn_v.weight=Q6_K' \
  --tensor-type 'blk.2.attn_output.weight=Q6_K' \
  --tensor-type 'blk.2.ffn_gate.weight=Q6_K' \
  --tensor-type 'blk.2.ffn_up.weight=Q6_K' \
  --tensor-type 'blk.2.ffn_down.weight=Q6_K' \
  --tensor-type 'blk.23.attn_q.weight=Q5_K' \
  --tensor-type 'blk.23.attn_k.weight=Q5_K' \
  --tensor-type 'blk.23.attn_v.weight=Q5_K' \
  --tensor-type 'blk.23.attn_output.weight=Q5_K' \
  --tensor-type 'blk.23.ffn_gate.weight=Q5_K' \
  --tensor-type 'blk.23.ffn_up.weight=Q5_K' \
  --tensor-type 'blk.23.ffn_down.weight=Q5_K' \
  --tensor-type 'blk.24.attn_q.weight=Q2_K' \
  --tensor-type 'blk.24.attn_k.weight=Q2_K' \
  --tensor-type 'blk.24.attn_v.weight=Q2_K' \
  --tensor-type 'blk.24.attn_output.weight=Q2_K' \
  --tensor-type 'blk.24.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.24.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.24.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.25.attn_q.weight=Q2_K' \
  --tensor-type 'blk.25.attn_k.weight=Q2_K' \
  --tensor-type 'blk.25.attn_v.weight=Q2_K' \
  --tensor-type 'blk.25.attn_output.weight=Q2_K' \
  --tensor-type 'blk.25.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.25.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.25.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.26.attn_q.weight=Q2_K' \
  --tensor-type 'blk.26.attn_k.weight=Q2_K' \
  --tensor-type 'blk.26.attn_v.weight=Q2_K' \
  --tensor-type 'blk.26.attn_output.weight=Q2_K' \
  --tensor-type 'blk.26.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.26.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.26.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.27.attn_q.weight=Q5_K' \
  --tensor-type 'blk.27.attn_k.weight=Q5_K' \
  --tensor-type 'blk.27.attn_v.weight=Q5_K' \
  --tensor-type 'blk.27.attn_output.weight=Q5_K' \
  --tensor-type 'blk.27.ffn_gate.weight=Q5_K' \
  --tensor-type 'blk.27.ffn_up.weight=Q5_K' \
  --tensor-type 'blk.27.ffn_down.weight=Q5_K' \
  --tensor-type 'blk.28.attn_q.weight=Q6_K' \
  --tensor-type 'blk.28.attn_k.weight=Q6_K' \
  --tensor-type 'blk.28.attn_v.weight=Q6_K' \
  --tensor-type 'blk.28.attn_output.weight=Q6_K' \
  --tensor-type 'blk.28.ffn_gate.weight=Q6_K' \
  --tensor-type 'blk.28.ffn_up.weight=Q6_K' \
  --tensor-type 'blk.28.ffn_down.weight=Q6_K' \
  --tensor-type 'blk.29.attn_q.weight=Q6_K' \
  --tensor-type 'blk.29.attn_k.weight=Q6_K' \
  --tensor-type 'blk.29.attn_v.weight=Q6_K' \
  --tensor-type 'blk.29.attn_output.weight=Q6_K' \
  --tensor-type 'blk.29.ffn_gate.weight=Q6_K' \
  --tensor-type 'blk.29.ffn_up.weight=Q6_K' \
  --tensor-type 'blk.29.ffn_down.weight=Q6_K' \
  --tensor-type 'blk.4.attn_q.weight=Q2_K' \
  --tensor-type 'blk.4.attn_k.weight=Q2_K' \
  --tensor-type 'blk.4.attn_v.weight=Q2_K' \
  --tensor-type 'blk.4.attn_output.weight=Q2_K' \
  --tensor-type 'blk.4.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.4.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.4.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.5.attn_q.weight=Q2_K' \
  --tensor-type 'blk.5.attn_k.weight=Q2_K' \
  --tensor-type 'blk.5.attn_v.weight=Q2_K' \
  --tensor-type 'blk.5.attn_output.weight=Q2_K' \
  --tensor-type 'blk.5.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.5.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.5.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.6.attn_q.weight=Q2_K' \
  --tensor-type 'blk.6.attn_k.weight=Q2_K' \
  --tensor-type 'blk.6.attn_v.weight=Q2_K' \
  --tensor-type 'blk.6.attn_output.weight=Q2_K' \
  --tensor-type 'blk.6.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.6.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.6.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.7.attn_q.weight=Q2_K' \
  --tensor-type 'blk.7.attn_k.weight=Q2_K' \
  --tensor-type 'blk.7.attn_v.weight=Q2_K' \
  --tensor-type 'blk.7.attn_output.weight=Q2_K' \
  --tensor-type 'blk.7.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.7.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.7.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.8.attn_q.weight=Q2_K' \
  --tensor-type 'blk.8.attn_k.weight=Q2_K' \
  --tensor-type 'blk.8.attn_v.weight=Q2_K' \
  --tensor-type 'blk.8.attn_output.weight=Q2_K' \
  --tensor-type 'blk.8.ffn_gate.weight=Q2_K' \
  --tensor-type 'blk.8.ffn_up.weight=Q2_K' \
  --tensor-type 'blk.8.ffn_down.weight=Q2_K' \
  --tensor-type 'blk.9.attn_q.weight=Q5_K' \
  --tensor-type 'blk.9.attn_k.weight=Q5_K' \
  --tensor-type 'blk.9.attn_v.weight=Q5_K' \
  --tensor-type 'blk.9.attn_output.weight=Q5_K' \
  --tensor-type 'blk.9.ffn_gate.weight=Q5_K' \
  --tensor-type 'blk.9.ffn_up.weight=Q5_K' \
  --tensor-type 'blk.9.ffn_down.weight=Q5_K' \
  --tensor-type 'token_embd.weight=Q5_K' \
  --tensor-type 'output.weight=Q5_K' \
  model-f16.gguf model-bitblame.gguf Q4_K_M

echo "recipe done -> model-bitblame.gguf"
Run it yourself: pip install git+https://github.com/habib-analyst/bitblame.git then
bitblame scan / probes / recipe / validate / report (see the repo README Quickstart).